ABSTRACT
Cybersecurity has become an important concern due to the increasing number of cyberattacks and unauthorized activities across computer networks. Detecting malicious network traffic accurately is essential for protecting sensitive information and maintaining network security. This project, titled “Cyber Breach Detection with Alert System Using Machine Learning,” proposes a machine learning-based approach to identify different types of network attacks using the CIC-IDS2017 dataset.
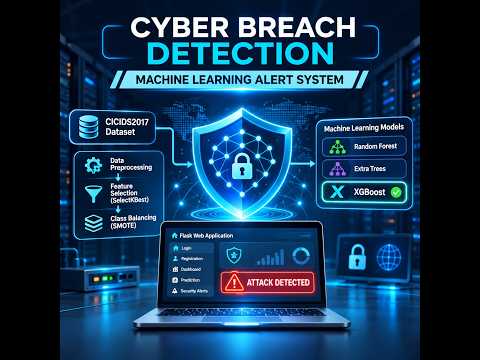
The system uses data preprocessing techniques such as handling missing values, removing unnecessary features, numerical feature selection, data scaling, and class balancing using the Synthetic Minority Over-sampling Technique (SMOTE). Three machine learning algorithms, namely Random Forest, Extra Trees, and XGBoost, are implemented and evaluated to identify the most suitable model for attack classification.
The experimental results show that XGBoost achieves the highest performance among the three models, with an accuracy of 97.45%, precision of 98.06%, recall of 97.45%, F1-score of 97.63%, and ROC-AUC of 0.9993. Based on the F1-score comparison, XGBoost is selected as the best-performing model.
A Flask-based web application is developed to provide user registration, login, attack prediction, and security alert management. The application predicts the attack category from the selected test dataset record and generates a security alert based on the prediction. BENIGN traffic is identified as SAFE, while non-BENIGN predictions are marked as ATTACK DETECTED. SQLite is used to store user information and generated security alerts.
The proposed system demonstrates how machine learning techniques can support network intrusion classification and security alert generation through a web-based interface.
INTRODUCTION
Cybersecurity has become one of the most important aspects of modern information technology due to the rapid development of computer networks, internet services, cloud computing, digital communication, and online applications. Today, individuals, educational institutions, government organisations, financial institutions, and business enterprises depend heavily on computer networks to store, process, and exchange information. These networks contain valuable information, including personal details, financial transactions, business records, confidential documents, and other sensitive data. Protecting such information from unauthorized access and malicious activities is a major challenge in the digital environment. As the number of connected devices and internet-based services continues to increase, the possibility of cyberattacks also increases. Therefore, identifying suspicious network activities and detecting cyber threats have become essential requirements for maintaining network security.
A cyberattack is an intentional attempt to access, damage, interrupt, or misuse a computer system, network, or digital resource. Cybercriminals use different techniques to exploit vulnerabilities in computer systems and gain unauthorized access to sensitive information. Some common network-based attacks include Denial of Service (DoS), Distributed Denial of Service (DDoS), port scanning, brute-force attacks, infiltration, and other malicious activities. These attacks can affect the normal functioning of network services and may result in data loss, service unavailability, financial damage, and privacy violations. For example, a Denial of Service attack attempts to make a network service unavailable by generating excessive traffic or requests. A port scanning activity can be used to identify open ports and available services on a target system. Brute-force attacks attempt to gain unauthorized access by trying different combinations of usernames and passwords. Such activities demonstrate the importance of analysing network traffic and identifying abnormal patterns.
Network traffic consists of the data packets and communication records exchanged between devices over a network. Each network communication can contain several characteristics, such as source and destination information, protocol details, packet sizes, flow duration, and other statistical features. Analysing these characteristics helps in understanding the behaviour of network communication. Normal network traffic generally represents legitimate communication between authorised devices and services, whereas malicious traffic may contain patterns associated with unauthorized or harmful activities. However, distinguishing normal traffic from malicious traffic is not always simple because different attack categories may have similar characteristics, and network environments may generate large volumes of data. Manual examination of every network record is time-consuming and difficult. This creates a need for automated techniques that can analyse network traffic efficiently and classify different types of activities.
Traditional network security mechanisms commonly use predefined rules, signatures, and known attack patterns to identify suspicious activities. These mechanisms can be useful for detecting previously identified threats. However, they may have limitations when dealing with new attack variations, changing network behaviour, and complex traffic patterns. Signature-based detection generally depends on previously recorded information about known attacks. If the characteristics of an attack change, the detection mechanism may fail to identify it using existing signatures. Similarly, rule-based systems require security rules to be created and maintained. As network environments become more complex, maintaining a large number of rules can become difficult. These limitations have encouraged the development of intelligent approaches that can analyse network data and identify patterns automatically.
Machine learning is an important branch of artificial intelligence that enables computer systems to learn patterns from data and make predictions without requiring every decision to be manually programmed. Machine learning algorithms can analyse large datasets, identify relationships between different features, and classify records based on patterns learned during training. In cybersecurity, machine learning techniques can be applied to network intrusion detection, malware classification, spam detection, anomaly identification, and other security-related tasks. By learning from previously collected network traffic records, a classification model can identify patterns associated with normal and malicious activities. This makes machine learning a useful approach for developing intelligent network attack detection systems.
The project titled "Cyber Breach Detection with Alert System Using Machine Learning" focuses on developing a machine learning-based system for identifying and classifying network attacks. The proposed project uses the CIC-IDS2017 dataset to train and evaluate different machine learning algorithms. The dataset contains network traffic records representing benign activities and different attack categories. These records provide numerical features that describe network communication behaviour. By analysing these features, the system learns to distinguish between different categories of network traffic. The main purpose of the project is to develop a classification model that can predict the attack category of a given network traffic record and generate a corresponding security alert through a web-based application.
The CIC-IDS2017 dataset is used as the primary data source for the proposed system. Network intrusion detection research requires datasets containing both normal and malicious traffic records so that machine learning algorithms can learn the differences between different categories. The dataset used in this project is named CICIDS2017_Balanced_40K_CORRECT.csv, and the target column is Attack_Type. The target column represents the category that the model must predict. The dataset contains several input features that describe network traffic characteristics. These features are used during the training process to identify patterns related to different attack categories. The dataset is prepared before being supplied to the classification algorithms to improve the consistency and quality of the input data.
Data preprocessing is an important stage in machine learning because raw datasets may contain missing values, unnecessary columns, infinite values, and features that do not contribute useful information to prediction. In this project, preprocessing is performed before training the classification models. The target and label-related columns are separated from the input features. Identifier-related columns, such as flow identifiers, source and destination IP addresses, MAC addresses, timestamps, dates, and time-related fields, are removed from the numerical feature set. Infinite values are replaced with missing values, and columns containing excessive missing values or constant values are removed. Numerical input features are retained for further processing. Missing numerical values are handled using median imputation. This helps maintain a consistent input structure for the machine learning models.
After preprocessing, the target attack categories are converted into numerical labels using label encoding. Machine learning algorithms require numerical representations of target classes for classification. Therefore, the LabelEncoder is used to transform the attack category names into corresponding numerical values. The dataset is then divided into training and testing subsets using a stratified 80:20 split. Stratification helps preserve the class distribution in both subsets. A fixed random state is used to make the data splitting process reproducible. The training subset is used to build the classification models, while the testing subset is used to evaluate their performance on records that were not used during training.
Feature selection is another important stage in the proposed system. A dataset may contain several input features, but not all features contribute equally to classification. Irrelevant or less informative features can increase computational requirements and may affect the learning process. To identify useful input features, the project uses the SelectKBest method with mutual information classification. Mutual information measures the relationship between input features and the target class. Based on the calculated scores, the system selects the top 40 features for model training. This reduces the input feature space while retaining the features considered most informative for the classification task. The feature selection process is fitted using the training data to maintain the separation between training and testing information.
Class imbalance is a common problem in network intrusion detection datasets. Some attack categories may contain more records than other categories. If a classification model is trained directly on an imbalanced dataset, it may become biased towards classes containing more samples. This can affect its ability to correctly classify categories with fewer records. To address this issue, the proposed system uses the Synthetic Minority Over-sampling Technique (SMOTE). SMOTE generates synthetic samples for minority classes using information from existing minority-class observations. In this project, SMOTE is applied only to the training data after preprocessing and feature selection. This helps improve the balance of class representation during model training without modifying the original testing data.
The proposed system implements three machine learning algorithms: Random Forest, Extra Trees, and XGBoost. These algorithms are selected to compare their classification performance on the prepared network traffic dataset. Random Forest is an ensemble learning algorithm that combines multiple decision trees to produce a final prediction. Each tree is trained using a different sample of the training data, and the final class is determined by combining the predictions of the individual trees. This approach helps reduce the limitations of relying on a single decision tree and provides a strong classification method for structured datasets.
Extra Trees, also known as Extremely Randomized Trees, is another tree-based ensemble learning algorithm. It builds multiple decision trees and introduces additional randomness during the tree construction process. Instead of selecting splits using only the most optimal threshold, the algorithm considers randomly selected splitting thresholds. The predictions from the individual trees are combined to produce the final classification result. This method provides another ensemble-based approach for comparing the performance of network attack classification.
XGBoost, or Extreme Gradient Boosting, is a gradient boosting algorithm that builds an ensemble of decision trees sequentially. Each new tree attempts to improve the prediction performance by learning from the errors made by the previously constructed trees. XGBoost includes regularisation and optimisation techniques that help improve model performance and control overfitting. It is widely used for structured and tabular datasets because it can learn complex relationships between input features. In this project, XGBoost is implemented with a multi-class classification objective to predict different network attack categories.
To identify the most suitable classification algorithm, all three models are evaluated using multiple performance metrics. These metrics include accuracy, precision, recall, F1-score, and Receiver Operating Characteristic Area Under the Curve (ROC-AUC). Accuracy measures the proportion of correctly classified records among all evaluated records. Precision measures how many records predicted as a particular class are correctly classified. Recall measures the proportion of actual records of a class that are correctly identified by the model. The F1-score combines precision and recall into a single measure using their harmonic mean. ROC-AUC evaluates the model's ability to distinguish between classes using the one-versus-rest approach for multi-class classification. Using multiple metrics provides a broader understanding of model performance than relying only on accuracy.
The experimental results obtained from the model comparison show that XGBoost achieves the highest performance among the three implemented algorithms. XGBoost obtains an accuracy of 97.45%, precision of 98.06%, recall of 97.45%, F1-score of 97.63%, and ROC-AUC of approximately 0.9993. Random Forest obtains an accuracy of 97.18% and an F1-score of 97.39%, while Extra Trees obtains an accuracy of 97.10% and an F1-score of 97.24%. Based on the comparison, XGBoost is selected as the best-performing model because it achieves the highest F1-score. The trained model and the associated preprocessing components are saved so that they can be loaded later by the web application for prediction.
In addition to model development, the project includes a web-based application developed using the Flask framework. Flask is a Python web framework that provides the required functionality for connecting the trained machine learning model with a web interface. The application allows users to register and log in before accessing the system's available pages. It provides separate sections for the dashboard, prediction, analysis, and project information. This web-based structure makes the classification functionality easier to access and provides an organised way to display prediction results and model performance information.
The prediction module is one of the main components of the web application. It loads the trained machine learning model along with the preprocessing objects, including the imputer, scaler, label encoder, and selected feature information. A test dataset record can be selected for prediction through the application. The selected record is processed using the same preprocessing sequence applied during model training. The imputer handles missing values, the scaler transforms the numerical features, and the feature selection information ensures that the model receives the expected input features. The trained XGBoost model then predicts the attack category and calculates the corresponding class probabilities. The highest predicted probability is used to determine the prediction confidence.
The alert generation module provides an additional security-related function based on the model's prediction. When the predicted attack category is BENIGN, the application identifies the record as SAFE and assigns NORMAL severity. When the predicted category is any non-BENIGN class, the application identifies the result as ATTACK DETECTED and assigns HIGH severity. The generated alert includes information such as the timestamp, selected record number, predicted attack type, severity, alert message, confidence value, and status. These alert details are stored in an SQLite database through the Flask application. This allows generated alerts to be maintained and accessed through the system.
SQLite is used as the database management system for storing application information. It provides a lightweight database solution that can be integrated with a Python-based web application. The database contains tables for user information and security alert records. The user table maintains registration-related information, while the security alerts table stores the alerts generated by the prediction module. By maintaining these records, the application provides a structured way to manage user access and retain prediction-related security information.
The dashboard and analysis modules provide information about the prepared dataset, training and testing records, selected features, best-performing model, and evaluation metrics. The application also presents model analysis information, including class distribution, confusion matrix, and classification report, where available in the trained model outputs. These details help users understand the performance of the selected classification model and examine its prediction behaviour. The dashboard provides an organised view of the system, while the analysis section supports the interpretation of the experimental results.
The proposed project combines machine learning-based classification with a web-based alert management mechanism. The training component focuses on preparing network traffic data, selecting relevant features, balancing the training classes, and comparing different machine learning algorithms. The web application focuses on loading the selected trained model, accepting a test dataset record for prediction, displaying the predicted attack category, and generating a security alert according to the prediction. This separation between model training and application-based prediction makes the system easier to organise and maintain.
The project is designed as a dataset-based cyber breach detection prototype. It uses prepared network traffic records from the CIC-IDS2017 dataset rather than directly capturing live packets from a computer network. Therefore, its current functionality demonstrates the classification of network traffic records and the generation of alerts based on machine learning predictions. The system provides a foundation for further development, where live network traffic capture, continuous monitoring, and integration with network security infrastructure can be considered as future enhancements.
Overall, the Cyber Breach Detection with Alert System Using Machine Learning project demonstrates how machine learning algorithms can be applied to network traffic classification and how the resulting predictions can be integrated into a web-based application. By implementing Random Forest, Extra Trees, and XGBoost, the project compares different classification approaches and identifies XGBoost as the best-performing model based on the experimental F1-score. The Flask application provides user authentication, prediction functionality, model analysis, and security alert storage using SQLite. The proposed approach offers an organised framework for analysing network traffic records, identifying potential attack categories, and presenting security-related information through a user-friendly interface.
Block Diagram