ABSTRACT
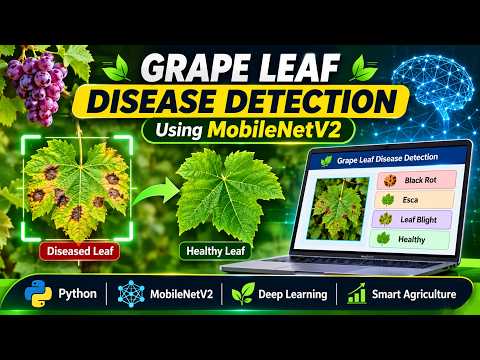
Grape cultivation is an important agricultural activity, and the identification of diseases at an early stage is essential for maintaining plant health and reducing potential crop losses. Grape leaves can be affected by different diseases that produce visible symptoms such as spots, discoloration, and changes in leaf appearance. Manual identification of these diseases generally depends on visual inspection and agricultural expertise, which can be time-consuming and may not provide consistent results. To address this problem, this project presents a machine-learning-based grape leaf disease detection system that uses image classification and MobileNetV2 analysis to support automated disease identification. The proposed system is designed to process grape-related data and evaluate classification performance using standard machine-learning metrics. The MobileNetV2 model is trained using a dataset stored in CSV format, where the target classification variable is automatically identified from the final column of the dataset. Categorical input attributes are converted into numerical representations using one-hot encoding, while the target labels are transformed using label encoding. The dataset is divided into training and testing subsets using an 80:20 ratio to evaluate the performance of the classification model. To study the effect of the number of decision trees on classification performance, multiple MobileNetV2 models are trained with estimator values ranging from 10 to 100. Each model is evaluated using accuracy and weighted F1-score, allowing the classification performance to be analyzed across different tree configurations. A final MobileNetV2 classifier containing 100 decision trees is trained and saved as a reusable model for subsequent prediction tasks. In addition to model development, the system automatically generates accuracy and F1-score performance graphs, which provide a visual representation of how model performance changes with the number of estimators. The trained model and generated evaluation results can be integrated into a larger grape leaf disease detection application to support automated classification and user-oriented prediction. The approach provides a structured machine-learning framework for analyzing disease-related grape leaf data and evaluating classifier performance. By combining data preprocessing, MobileNetV2 classification, performance evaluation, and model persistence, the proposed system establishes a practical foundation for an intelligent grape leaf disease detection solution. The developed approach can further be extended with image-based deep-learning models, additional grape disease categories, larger datasets, and web-based prediction interfaces to improve the applicability of automated disease diagnosis in agricultural environments.
INTRODUCTION
Grape cultivation is an important agricultural activity that contributes significantly to food production, fruit processing, and the agricultural economy. The quality and productivity of grape crops are strongly influenced by the health condition of the plants. Among the different parts of a grape plant, leaves provide important visual indicators of plant health because many diseases produce visible symptoms on the leaf surface before severe damage occurs to the entire plant. Symptoms such as dark spots, lesions, discoloration, and changes in leaf texture can indicate the presence of specific grape diseases. Therefore, early and accurate identification of grape leaf diseases is important for preventing disease progression and supporting appropriate crop-management practices. When diseases are detected at an early stage, suitable management measures can be considered before the infection spreads extensively throughout the vineyard.
Traditional grape leaf disease identification is commonly performed through visual observation of plant symptoms. Farmers or agricultural experts examine the appearance of leaves and compare the observed symptoms with known disease characteristics. Although this approach can be useful when experienced personnel are available, manual identification can be time-consuming when a large number of plants must be inspected. The accuracy of visual diagnosis can also depend on the experience of the person performing the inspection and the quality of the available leaf samples. Similar visual symptoms may occur in different diseases, making classification more difficult when the disease is at an early stage. These challenges create a need for automated computational approaches that can analyze grape leaf information and provide consistent classification results.
The development of machine learning and computer vision has created new possibilities for automated agricultural disease detection. Machine-learning algorithms can learn patterns from previously collected data and use those patterns to classify new observations. In an agricultural disease-detection system, relevant features associated with healthy and diseased plants can be represented in a structured dataset and supplied to a classification algorithm. Once trained, the algorithm can identify patterns associated with different target classes and generate predictions for previously unseen data. Such approaches can reduce dependence on manual analysis and provide a computational foundation for intelligent agricultural applications. The effectiveness of a machine-learning model, however, depends on factors such as the quality of the dataset, preprocessing methods, feature representation, training strategy, and appropriate evaluation metrics.
This project focuses on the development of a grape leaf disease detection approach using the MobileNetV2 classification algorithm. MobileNetV2 is an ensemble machine-learning technique that combines the predictions of multiple decision trees to produce a final classification result. Instead of relying on a single decision tree, the algorithm creates multiple trees and aggregates their predictions. This ensemble strategy provides a systematic approach for handling classification problems and can be applied to datasets containing numerical as well as categorical attributes. In the proposed implementation, the input dataset is stored in a CSV file, and the final column of the dataset is automatically considered the target classification variable. The remaining columns are treated as input features for model training and evaluation.
Data preprocessing is an important stage of the proposed system because machine-learning algorithms require suitable numerical representations of the input information. When categorical attributes are present in the dataset, they cannot be directly processed in their original textual form by the MobileNetV2 implementation. Therefore, categorical input features are converted into numerical representations using one-hot encoding. The target classification labels are also converted into numerical values using a label-encoding process. This preprocessing step creates a machine-readable feature matrix while maintaining the information required for classification. The prepared dataset is subsequently divided into training and testing subsets, with 80 percent of the data used for training and 20 percent reserved for testing. This separation allows the trained model to be evaluated using data that was not directly used during model learning.
The MobileNetV2 model is evaluated using different numbers of decision trees to study the relationship between model complexity and classification performance. In the implementation, models are trained using estimator values ranging from 10 to 100 trees in increments of 10. For every configuration, the model is trained using the training dataset and predictions are generated for the test dataset. The predicted results are compared with the actual target labels using accuracy and weighted F1-score. Accuracy provides an overall measure of the proportion of correctly classified samples, while the weighted F1-score provides a combined measurement of precision and recall while considering the contribution of different classes. Evaluating both measures provides a broader understanding of classification performance rather than depending on a single metric.
After evaluating the different configurations, a final MobileNetV2 classifier containing 100 estimators is trained using the training data. The resulting model is saved as a reusable machine-learning file using the Joblib library. Saving the trained model is important because it allows the learned classifier to be reused for future prediction tasks without retraining the complete model each time. The implementation also produces graphical representations of the experimental results. An accuracy graph illustrates the change in classification accuracy as the number of MobileNetV2 trees increases, while an F1-score graph represents the corresponding change in weighted F1-score. These graphs provide a visual method for examining model behavior across the evaluated estimator configurations.
The proposed machine-learning approach forms one component of a broader grape leaf disease detection system. The classification model can be integrated with an image-based disease detection application in which grape leaf images are processed and the resulting disease-related information is presented to users. In a practical agricultural environment, such a system can provide a computational aid for preliminary disease identification and support timely decision-making. The use of a trained classification model also provides the possibility of integrating automated prediction into a web-based application, allowing users to interact with the system through a simple interface rather than directly executing machine-learning code.
The overall objective of this project is to develop a systematic and automated approach for grape leaf disease classification by combining data preprocessing, MobileNetV2 learning, model evaluation, and model persistence. The approach emphasizes measurable classification performance through accuracy and weighted F1-score and provides graphical analysis for different numbers of estimators. The resulting framework can serve as a foundation for further development of intelligent grape disease detection systems. Future extensions can incorporate larger and more diverse datasets, additional grape disease categories, image-based deep-learning architectures, automated feature extraction, and web-based prediction functionality. Such extensions can improve the ability of the system to process real-world grape leaf images and make the technology more applicable to agricultural disease-monitoring scenarios. Overall, the project demonstrates the application of machine-learning techniques to grape leaf disease detection and establishes a structured framework for developing automated and data-driven agricultural classification systems.
Block Diagram